 Phone : +974 44420050

 Doha, Qatar



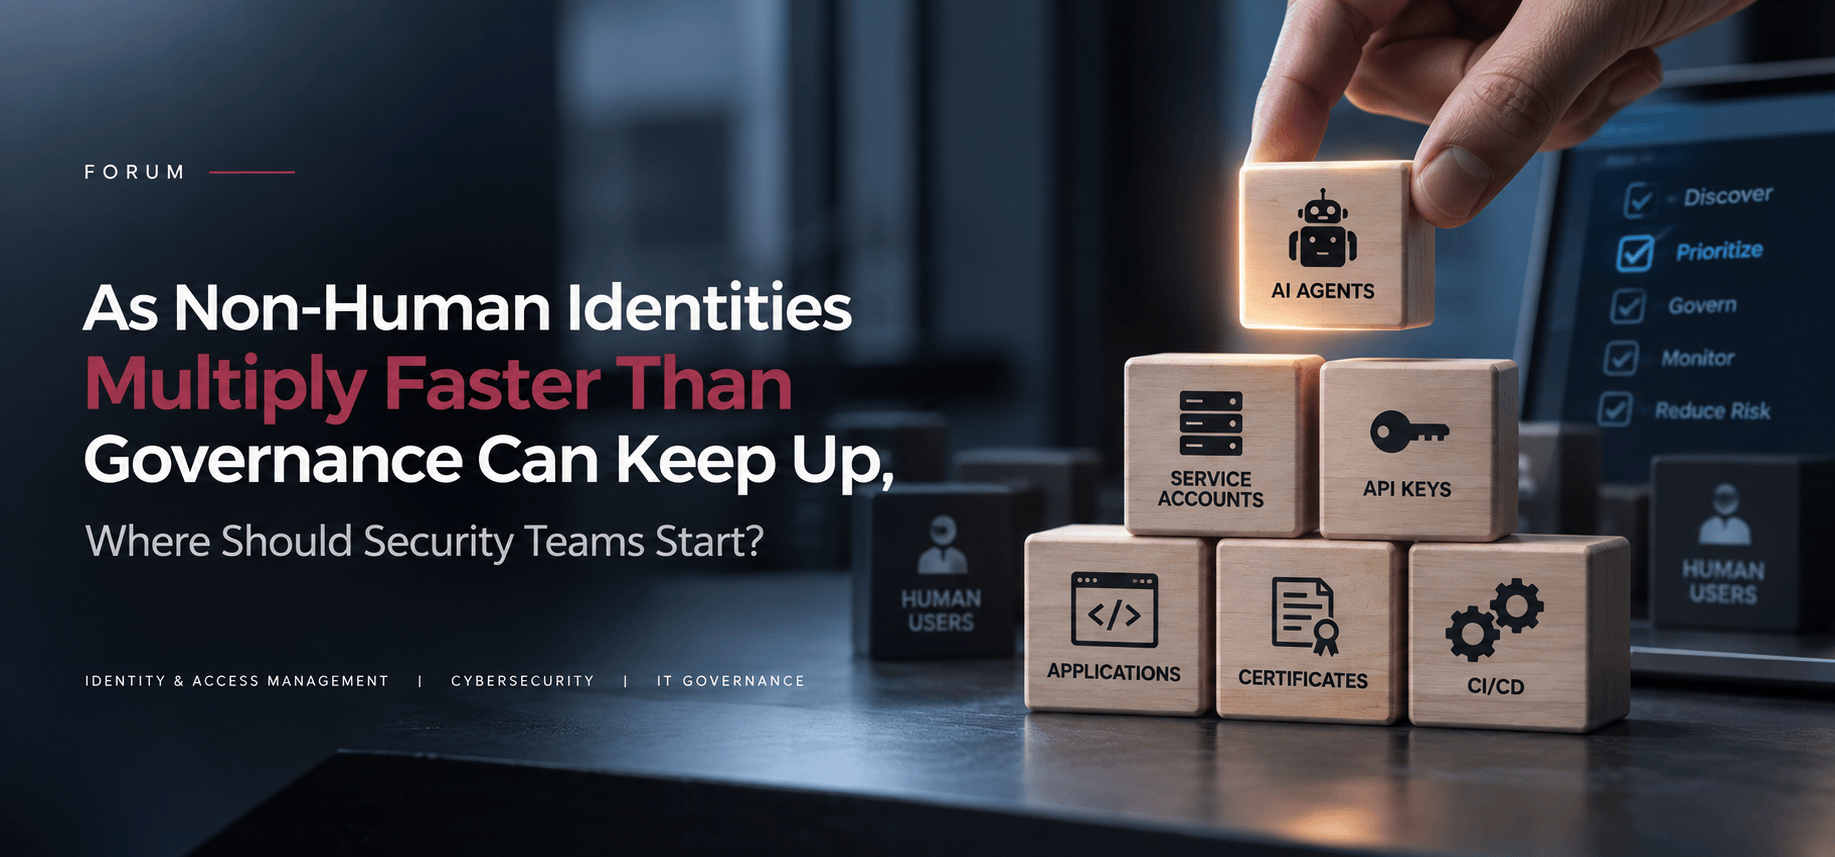
Most enterprise environments now contain far more non-human identities, service accounts, API keys, certificates, and increasingly AI agents, than human user accounts. Estimates of exactly how many more vary widely across recent research, but the direction is consistent: the gap is large and growing faster than most identity programs were built to handle.
That creates a genuine prioritization problem. Discovering and fully governing every non-human identity in a large enterprise environment is not realistic in the short term, and treating it as an all-or-nothing initiative tends to stall before it produces results. So the more useful question for security teams right now may not be how to secure every non-human identity, but which ones to secure first.
A few angles worth discussing:
Should prioritization start with the identities that hold the highest privileges, regardless of how actively they are used, or with the identities that are most actively used, regardless of privilege level? How should a security team weigh an old, dormant service account with broad access against a newly created AI agent identity with narrower but rapidly expanding permissions? Is discovery itself the bottleneck, meaning teams cannot prioritize what they cannot yet see, or is the harder problem what to do once discovery is complete? And practically, whose job is this: identity and access management teams, the application or platform teams that create these identities in the first place, or some shared model that most organizations have not yet built?
There is no single accepted framework for this yet across the industry, which is exactly why it is worth comparing notes.
If you had to secure only 20 percent of your organization's non-human identities this quarter, which 20 percent would you choose, and why?



 Celebrating Excellence: Mr. Syed Rizwan ...