 Phone : +974 44420050

 Doha, Qatar




Artificial
intelligence has moved from pilot projects to core business functions across
GCC enterprises. Customer service, document processing, fraud detection,
forecasting, and internal knowledge tools increasingly rely on AI models to
operate.
That shift
raises a question that many organizations address too late: where does the data
actually go once it enters an AI system?
Data residency
has always mattered for regulated industries such as banking, government,
healthcare, and telecommunications. AI complicates the picture because it
introduces new data flows that traditional residency planning did not
anticipate, including prompts, model outputs, embeddings, logs, and fine-tuning
datasets.
For enterprises
operating in Qatar and across the wider Gulf region, getting this right is not
only a compliance exercise. It is a foundational requirement for scaling AI
safely and sustainably.
Enterprise
architects and CISOs are increasingly being asked to answer this question with
precision, not generalities. Regulators, auditors, and boards want to know not
just that an organization is using AI responsibly, but exactly where the
underlying data travels, who can access it, and how long it is retained at each
stage of the process.
Conventional
data residency planning focuses on where a database physically sits. AI systems
introduce a second, less visible data path: the journey a piece of information
takes every time it is sent to a model for processing.
When an
application sends a customer record, a contract clause, or an internal report
to a large language model for analysis or generation, that data leaves its
original storage location, even if only briefly. If the model is hosted outside
the country or region, the data has effectively crossed a border, regardless of
where the surrounding application runs.
This applies to
more than the original request. Prompts, responses, embeddings created for
retrieval, and logs generated for monitoring or debugging can all carry
sensitive information, and each represents a separate data flow that needs to
be accounted for.
Qatar and its
neighbors are actively building AI governance frameworks rather than waiting
for global standards to settle. Qatar's National Artificial Intelligence
Strategy, guidance from the National Cyber Security Agency, and the existing
Personal Data Privacy Protection Law already shape how organizations must
handle data used in AI systems, even without a single dedicated AI law in
place.
Sector
regulators, particularly in finance and government services, are moving faster
than horizontal legislation. Central banks and financial regulators across the
region have introduced AI-specific guidance for their sectors, and
public-sector procurement increasingly expects vendors to demonstrate
responsible AI practices.
Sovereign and
in-region cloud initiatives are also expanding, giving enterprises more
practical options for keeping AI workloads within national or regional borders.
This trend is likely to continue as governments treat AI infrastructure as a
matter of digital sovereignty as well as economic policy.
Regulatory
frameworks in this space are still evolving, so enterprises should treat this
as an area to monitor continuously rather than a checklist to complete once.
Legal counsel should always be involved when interpreting specific obligations
for a given sector or jurisdiction, particularly as guidance shifts from
voluntary frameworks toward more formal, sector-specific requirements over the
coming years.
This evolving
landscape means that an architecture judged compliant today may need to be
revisited as new guidance is published. Building flexibility into the
underlying data and AI architecture, rather than hard-coding assumptions about
today's rules, reduces the cost of adapting later.
Before choosing
an architecture, organizations need clarity on what kind of data they are
actually working with. A practical classification model typically includes:
Public and
low-sensitivity internal data can often use broader AI deployment options,
including globally hosted models, with appropriate contractual and security
controls. Regulated data typically requires stricter architecture choices, and
in many cases should never leave the country or region in raw form.
Enterprises
handling regulated data generally have three architectural paths available,
often used in combination:
Retrieval-based
designs are particularly useful because they limit how much sensitive data is
exposed to a model at any point, compared to approaches that fine-tune a model
directly on regulated datasets. Prompts, logs, and embeddings generated during
these interactions should be governed with the same rigor as the original data
source, including encryption, access controls, and defined retention periods.
Technical
architecture solves part of the problem. Governance solves the rest. A
practical AI data governance program should include:
Without this
layer, even a well-designed in-region architecture can drift out of compliance
as new use cases, integrations, and vendors are added over time.
Organizations
do not need to solve every AI governance question before beginning. A more
realistic starting point is to:
This creates a
foundation that can scale as AI adoption grows, rather than a governance
structure built after problems have already appeared.
A few patterns
show up repeatedly in organizations that end up addressing AI data residency
after the fact rather than by design.
Each of these
is avoidable with a governance process that treats data residency as an ongoing
discipline rather than a one-time approval step completed before launch.
AI data
residency and governance are not separate from AI strategy. They are part of
it. Enterprises that treat data classification, architecture, and governance as
day-one design decisions are better positioned to scale AI confidently, meet
regulatory expectations, and maintain the trust of customers, partners, and
regulators.
The
organizations that struggle later are usually the ones that treated residency
as a legal question to answer after deployment, rather than an architectural
question to answer before it.
At Proz
Technologies, cloud architecture, data governance, cybersecurity, and
enterprise IT consulting can help organizations design AI environments that
align with regional regulatory expectations while still delivering real
business value.


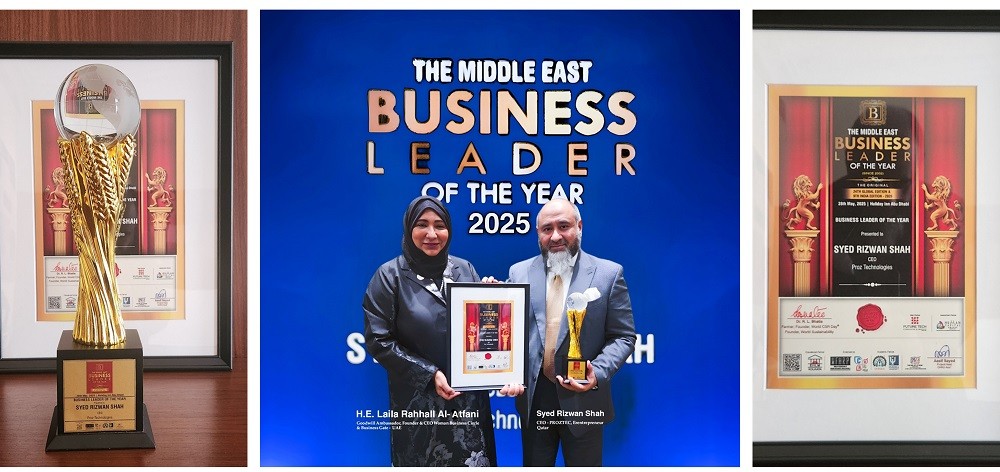 Celebrating Excellence: Mr. Syed Rizwan ...